Local models / recorded use
Which models, for which jobs?
Routing below reflects the 25 October build records; the three Qwen installations were checked on 26 October. Each role is scoped to its observed work. These are development results, not a general model leaderboard.
Primary local coder
Qwen3 Coder Next
Ollama · Q4_K_M · 65,536 tool-worker context
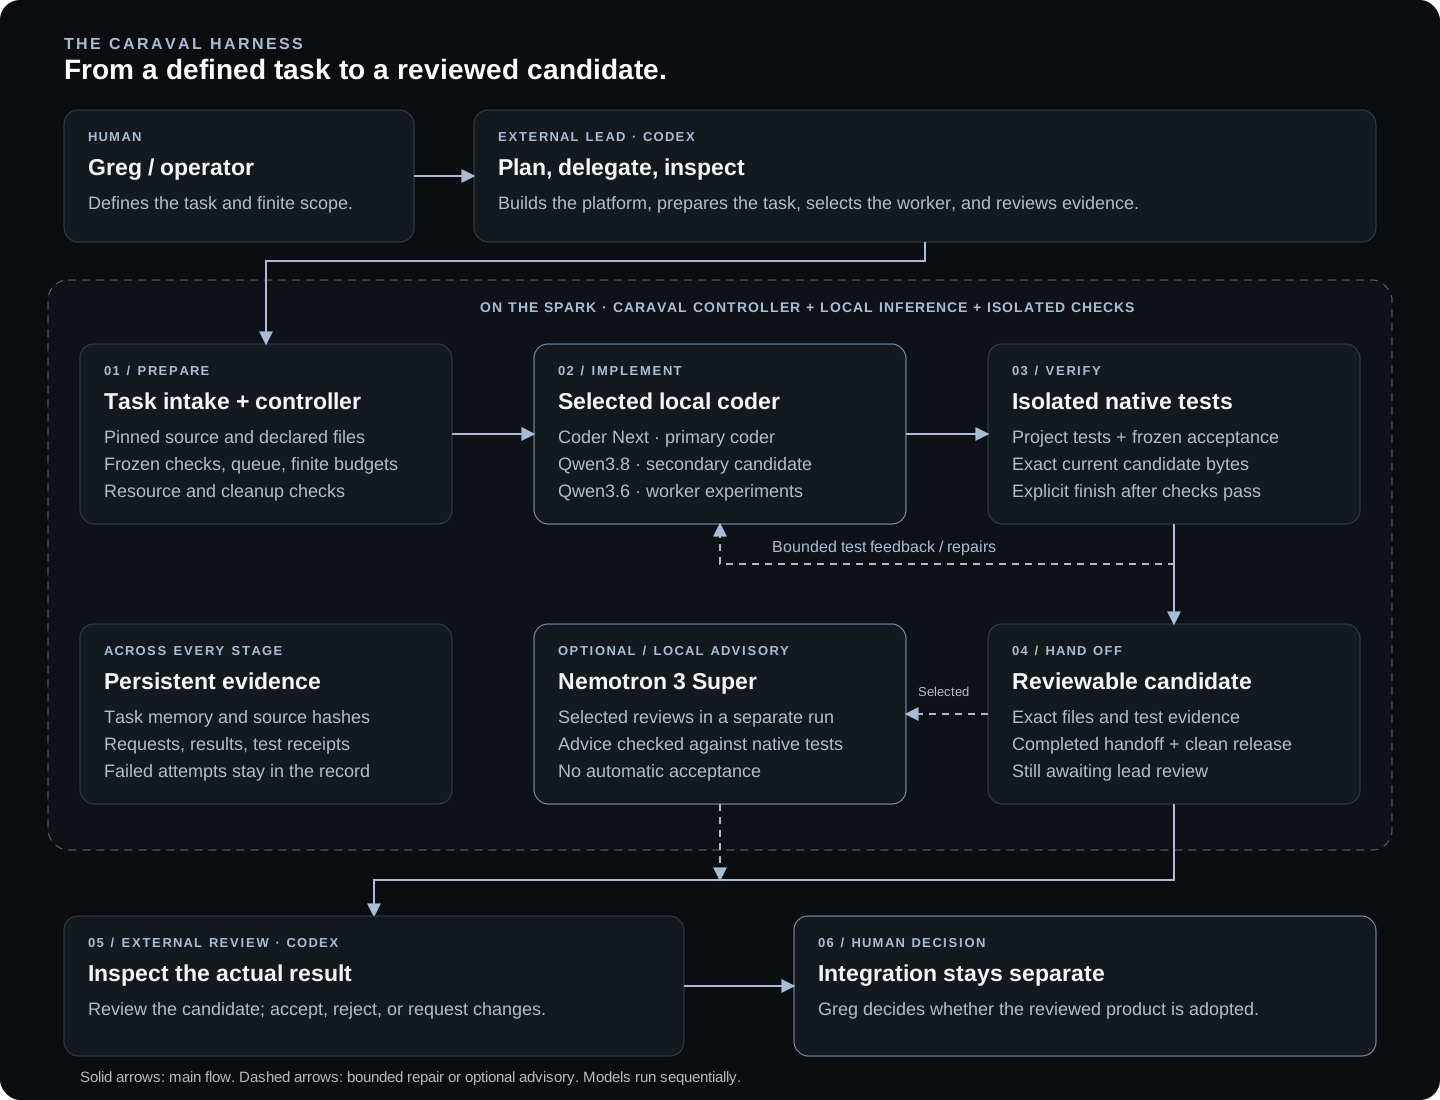
Used for small, explicitly scoped implementation tasks. Its JSON-action route makes edits, checks, and completion visible to the controller.
Observed: A supervised three-task RepoScout batch completed with one worker correction and no lead implementation corrections. Combined source passed 101 tests plus three frozen acceptance checks.
Limit: Codex still reviews the actual candidate. Other tasks have needed lead corrections or stopped before completion.
Secondary coding candidate
Qwen3.8 27B
Ollama · Q4_K_M · 65,536 tool-worker context
An explicitly selected alternative for bounded coding work; it is not an automatic fallback.
Observed: Completed a frozen RepoScout selection task in five responses with no corrections. Original and restored source passed 77 tests plus frozen acceptance; the lead accepted it without code edits.
Limit: A separate review trial falsely accepted known defective code. Coding success does not qualify it as the sole reviewer.
Advisory + worker experiments
Qwen3.6 35B A3B
Ollama · Q4_K_M · 32,768 tool-worker context
The default tool-worker profile in the configuration, also used in a separate small advisory lane. Practical primary coding currently goes to Coder Next.
Observed: A context-continuation repair enabled a bounded worker task to finish with passing checks. Earlier failed and context-blocked runs remain in the record.
Limit: The seven-case advisory evaluation completed but failed its full quality rubric: it missed a required failure mode and made incorrect claims about two correct controls.
Selected advisory reviewer
NVIDIA Nemotron 3 Super 120B A12B
vLLM · NVFP4 model · 65,536 recorded context
Run separately for selected bounded reviews, with native tests and Codex adjudication. It is not an always-on stage after every edit.
Observed: Accepted a correct RepoScout selector and rejected a deliberately broken version with a witness that Codex reproduced. Both review results were accepted for that two-case trial.
Limit: Cold startup took about ten minutes and the run recorded memory pressure and swap activity. The defect was already detectable by native tests; added detection beyond tests is unproven.
Context figures describe these configured routes, not maximum model capability. Models are selected for an explicit run and used sequentially; this diagram does not imply concurrent GPU serving or automatic model switching.
Earlier experiments / 28 September
Models tested before the current routing.
GLM-4.5-Air · Q4_K_M
Tested as a different-family reviewer in the original Spark harness. It passed 3 of 5 small smoke checks; standalone coding and arithmetic failures were retained. Its review was kept secondary to executable tests and human judgement.
GPT-OSS 120B · MXFP4
Tested for heavier reasoning in the early local-model setup. It passed 5 of 5 small smoke checks. Those results establish that narrow test run, not current routing or general coding accuracy.
Both are historical tests. Neither appeared in the current Ollama inventory checked for this update. No model was started or benchmark rerun to prepare this page.